 中文
电脑版
Edge intelligence · nothing leaves the plant
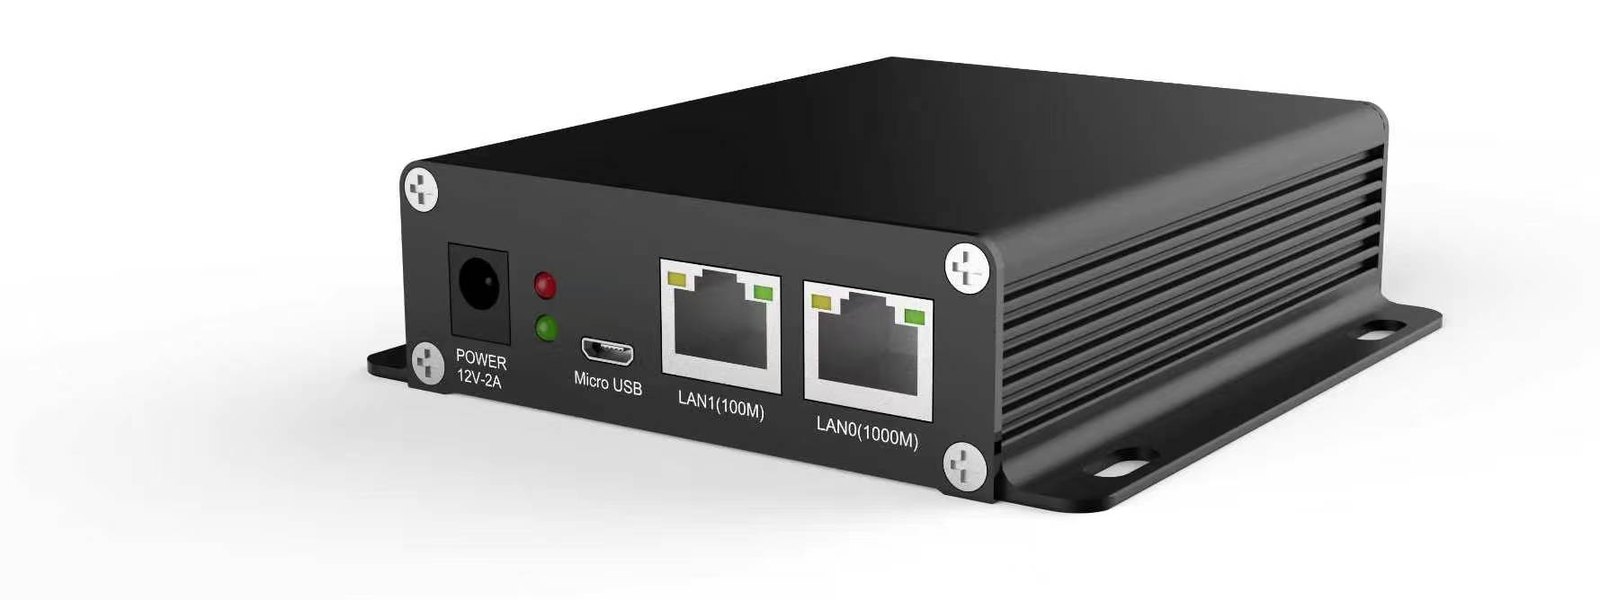
A self-contained appliance running a 27-billion-parameter language model and the OpenClaw agent runtime locally. Four concurrent sessions, 40+ tokens per second in total, about 58 W average — no cloud account, no data leaving the network.
27BLanguage model resident on the appliance
4Concurrent agent sessions
40+Tokens per second, aggregate
58 WAverage system power, measured
Plant data — P&ID sets, maintenance logs, meter readings, operator notes, photographs of a failed bearing — is exactly the data that a security review will not let out of the building. An agent that needs the internet to answer a question about a pump is an agent that will not be deployed.
This appliance answers locally. The model, the documents, the conversation history and the tool results all stay inside the plant network. There is no per-token bill and no dependency on a vendor staying in business or keeping an API online.
Measured, not estimated. The performance figures on this page were recorded on our reference unit: 4-way concurrent generation at 8K context per session, 10.4–10.9 tokens/s per stream, NPU utilisation reaching 99%, hottest point 52 °C, about 1.5 GB of the 15.6 GB memory in use.
Configuration
HostRK3588, 8-core
Accelerators4 × RK1828
AI throughput20 TOPS INT8 / 40 TOPS INT4 per card
Memory15.6 GB visible, 4 × 5 GB stacked
Network1 × GbE + 1 × 100M, optional 4G/5G
Power12–36 V DC, ~58 W average
EnclosureDesktop or DIN-rail, fanless option
Measured performance
27B model, W4A16 quantisation, 8K context per session, four sessions generating simultaneously.
| Metric | Measured | Note |
|---|---|---|
| Time to first token | 0.9–2.6 s | Per session, four running in parallel |
| Decode speed per session | 10.4–10.9 tokens/s | Stable across the run |
| Aggregate throughput | 40+ tokens/s | Four sessions combined |
| NPU utilisation | 83 → 99% | Saturates as all four streams fill |
| Memory in use | 1.2–1.6 GB of 15.6 GB | Leaves headroom for a larger context |
| Temperature | 32–52 °C | Host 32–41 °C, accelerators 38–52 °C |
| Long-context mode | 32K per session, 2 sessions | About 6.5 GB per card at 32K |
A single session runs faster than 10 tokens/s; the figure above is the per-stream rate with four sessions sharing the hardware. Context length trades against concurrency — the appliance is configured for whichever your workload needs.
Industrial use
◍
Vibration and acoustic data ingested locally, trend summaries and anomaly notes written in plain language for the maintenance team.
▤
Meter data collected, specific energy calculated per unit of output, and the weekly saving report drafted before the meeting.
≋
Drainage and ventilation readings summarised against limits, with exceptions flagged instead of buried in a spreadsheet.
⌁
Manuals, drawings and past work orders searchable in natural language — including photographs of nameplates and damage.
◷
Handover notes, production summaries and incident drafts generated from the data the plant already records.
✦
Selection checks, pump sizing and quotation drafts produced on site, without a connection back to head office.
The appliance is delivered configured, with the model loaded and the agent runtime installed. Commissioning is a network drop and an account setup, not a software project.
It is not a replacement for a plant historian, a DCS or a safety system. It reads, summarises and drafts; it does not close a control loop, and it is not connected to protection logic.
It is also not an unlimited model. A 27B model on edge silicon is a capable assistant for engineering and reporting work — it is not a frontier model, and we do not present it as one. The value is that it runs here, on your data, at a fixed cost, with no network dependency.
The appliance is built on Rockchip's standard edge product family — an RK3588 host with RK1828 accelerator modules, the same silicon any integrator can buy. The hardware is not the product.
What we deliver is everything above it: the model chosen and quantised for the duty, the OpenClaw agent runtime, the document index, the tool connections, the prompts and the guardrails that make it answer like a plant engineer instead of a chatbot — plus the people who pick up the phone when it does not.
Same box, your brand. For distributors and system integrators we ship the appliance configured and tested, with your nameplate, your start screen and your support contact. You sell it into your market; we keep the runtime and the knowledge base current.
Our first export markets are the ASEAN countries and Southeast Asia, where a plant often has the machines and the meters but not the bandwidth, the budget or the data-protection clearance for a cloud AI service. An appliance that runs on 58 W, needs no internet and answers in the local language fits those sites.
Tell us the documents you want it to read and the questions you want answered. We will demonstrate it on your own files, offline.
Arrange a demonstration大连宏实科技有限公司 · DALIAN HONGSHI TECHNOLOGY
© 2026 · Mobile edition · 手机版